Chapter 1 Variables and accumulation

Section 1.1 Variables, constants, and parameters

The use of symbols and alphabetic letters to represent numbers both known and unknown dates back millennia and was practised in numerous ancient cultures around the world.
We often use letters or symbols to represent quantities that maintain a constant value, which we (unsurprisingly) refer to as constants. Two familiar examples are the use of the Greek letter \(\pi \) to represent the common ratio of circumference to diameter that every circle exhibits and the use of the ordinary letter \(c \) to represent the speed of light in a vacuum.
While \(\pi \) and \(c \) are “known” constants (to the extent that the value of \(\pi \) can be “known”), an unknown value is sometimes referred to as a constant as well, and is assigned a letter like \(C \) or \(K \) to represent it, in the case the unknown value is known or assumed to be literally constant (unchanging) in its context. For example, a pair of parallel lines remain the same, fixed, perpendicular distance \(d \) apart along their lengths. While we have chosen to use a “variable” \(d \) to represent this value, it is unchanging in its context of two particular lines: no matter what perpendicular segment between the two lines is considered, the length \(d \) of that segment is always the same. However, it is an unknown constant as it is dependent on the particular pair of lines considered — a different pair of parallel lines might have a different constant distance \(d \) between them.
A quantity whose value can be controlled is often referred to as a parameter. It often represents a choice that can be made in creating or defining some mathematical object, and can be used to parametrize (or index) the entire collection of objects that can be created. For example, the collection of all lines in the Cartesian \(xy \)-plane that pass through the origin can be parametrized by their slopes — for each slope value \(m \text{,}\) we can create a line through the origin with equation
\begin{equation*} y = m x \text{.} \end{equation*}
For a particular such line the slope value \(m \) is constant, but a different slope creates a different line.
The letters \(x \) and \(y \) in the line-equation example above play a different role than the letter \(m \text{.}\) A line is a collection of points, and we think of these points as being at varying positions along the line, where \(x \) and \(y \) represent the coordinates of any one of these points. Any quantity that can vary will be represented by a variable.
Of course, how we categorize a quantity is based on point of view — a single line has a constant slope, it’s when we want to consider a family of lines with the same form of equation that slope becomes a parameter. How we refer to any letter that represents a quantity — as constant, parameter, or variable — indicates to the reader or listener a particular role that we wish that letter to play.

Section 1.2 Accumulation

When a quantity is variable, we often want to compare its values at different data points to identify trends. When the quantity grows larger, we think of it as accumulating, and when it becomes smaller, we think of it as diminishing or dissipating. However, we will use the same word accumulation for both situations, using positive and negative to distinguish between the two.

Definition 1.2.1. Accumulation of a variable quantity.

For variable quantity \(q \text{,}\) the accumulation between data points \(q_1 \) and \(q_2 \) is
\begin{equation*} \change{q} = q_2 - q_1 \text{.} \end{equation*}
We can interpret this formula in words as
\begin{equation*} \text{accumulation} = (\text{final quantity}) - (\text{initial quantity}) \text{.} \end{equation*}

Example 1.2.2. Accumulation of snow.

Here is a situation familiar to residents of the Canadian Prairies: a weather forecast predicting 20 cm of snow overnight. But this measurement does not take into account the existing snow pack on the ground — it only represents the additional height of snow that will be present in the morning, on top of the existing snow pack already on the ground the previous evening. And we would say that 20 cm of snow accumulated overnight, again not including any existing snow pack measurement in that statement.
Notice the following.
\begin{align*} q_2 \gt q_1 \amp \implies \change{q} \gt 0 \\ q_2 \lt q_1 \amp \implies \change{q} \lt 0 \end{align*}
So a positive accumulation indicates that the quantity has increased from the first to second data points, and a negative accumulation indicates that the quantity has decreased.

Example 1.2.3. Accumulation of rain.

You leave a one litre container out in the rain, and when the rain stops it is a quarter-full. A few days of sunny weather later and half of that has evaporated. So over the rainy period the accumulation in millilitres was approximately
\begin{align*} \change{q} \amp = q_2 - q_1 \\ \amp = 250 - 0 \\ \amp = 250 \text{,} \end{align*}
while over the sunny period the accumulation was approximately
\begin{align*} \change{q} \amp = q_3 - q_2 \\ \amp = 125 - 250 \\ \amp = - 125 \text{.} \end{align*}
In this course we will develop a method (called integration) that allows us to measure accumulation without knowing the initial or final amounts, but instead from the knowledge of how “fast” the accumulation is occurring. We would then like to use this information to recover the final amount, but in that case we will need to at least know the initial amount.

Example 1.2.5. Final amount of snow.

Let’s return to the situation of Example 1.2.2, where 20 cm is expected to fall overnight. You still haven’t cleared your driveway from the previous snow fall. In the evening, before the new snow has begun to fall, you go out to measure the depth of snow in your driveway and find that it is 17 cm.
If \(h \) represents the (variable) height of the snow in your driveway in centimetres, then we now have two pieces of information: a data point \(h_1 = 17 \) measured in the evening, and the accumulation of height \(\change{h} = 20 \) expected overnight. From these two pieces of information we can extrapolate a second data point to be verified in the morning:
\begin{align*} h_2 \amp = h_1 + \change{h} \\ \amp = 17 + 20 \\ \amp = 37 \text{.} \end{align*}

Section 1.3 Rate of accumulation

It is often the case that two quantities accumulate in tandem, and we wish to compare the relative amount of accumulation between data points.

Example 1.3.1. Volume versus depth.

A graduated cylinder is a vessel for measuring a volume of liquid using a ruled scale printed vertically on its side. It works because at a constant diameter, the volume can be directly related to depth by
\begin{equation*} V = \frac{\pi d^2 h}{4} \text{,} \end{equation*}
where \(d \) is the diameter and \(h \) is the depth (or height) in the cylinder.
When designing a graduated cylinder for manufacture, what diameter should be chosen so that the ruled markings can be printed as millimetres, with each centimetre of depth corresponding to \(10 \) cubic centimetres of volume? A variation in depth corresponds to a variation in volume, so that for two different depths \(h_1 \) and \(h_2 \) with corresponding volumes \(V_1 \) and \(V_2 \text{,}\) we have
\begin{align*} \change{V} \amp = V_2 - V_1 \\ \amp = \frac{\pi d^2 h_2}{4} - \frac{\pi d^2 h_1}{4} \\ \amp = \frac{\pi d^2}{4} (h_2 - h_1) \\ \amp = \frac{\pi d^2}{4} \change{h} \text{.} \end{align*}
If we turn this into a ratio \(\inlineslope{V}{h} \text{,}\) we can directly see how a variation in depth leads to a variation in volume.
\begin{equation*} \slope{V}{h} = \frac{\pi d^2}{4} \text{.} \end{equation*}
We can think of this ratio as describing variation in volume per unit variation in depth. This is because if \(\change{h} = 1 \text{,}\) then
\begin{equation*} \slope{V}{h} = \frac{\change{V}}{1} = \change{V} \text{.} \end{equation*}
So whenever the depth varies by \(1 \) centimetre, the volume will vary by
\begin{equation*} \frac{\pi d^2}{4} \end{equation*}
cubic centimetres. But if the depth varies by \(20 \) centimetres, then the volume will vary by
\begin{equation*} 20 \cdot \frac{\pi d^2}{4} = 5 \pi d^2 \end{equation*}
cubic centimetres.
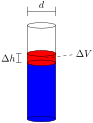
A diagram illustrating a variation in liquid depth in a cylinder accompanied by corresponding variation in volume.
A tall cylinder of diameter \(d \) is pictured, partially filled with a blue liquid. An additional volume of red liquid sits atop the blue liquid, and is labelled \(\change{V} \text{.}\) The additional height of the red liquid (from the top of the blue liquid to the top of the red liquid) is labelled as \(\change{h} \text{.}\)
Figure 1.3.2. Variation in liquid depth in a cylinder accompanied by corresponding variation in volume.
We can now answer the original question: each centimetre variation in depth corresponds to \(10 \) cubic centimetres variation in volume, which can be represented in mathematical notation as
\begin{equation*} \slope{V}{h} = 10 \end{equation*}
if was assume that both the diameter \(d \) and the depth \(h \) are measured in centimetres. Solving, we obtain
\begin{align*} \frac{\pi d^2}{4} \amp = 10 \\ d^2 \amp = \frac{40}{\pi} \\ d \amp = 2 \sqrt{\frac{10}{\pi}} \text{,} \end{align*}
where we discard the negative solution since we want diameter to be a positive quantity. So the diameter should be approximately 3.57 cm.
Definition 1.3.3. Average rate of accumulation.

If \(q \) and \(t \) are two quantities that are accumulating in tandem, so that a variation in one of the quantities is always accompanied by a corresponding variation in the other, then a ratio
\begin{equation*} \avg{r} = \slope{q}{t} = \frac{q_2 - q_1}{t_2 - t_1} \end{equation*}
is called an (average) rate of accumulation or (average) rate of variation between data points \((t_1,q_1) \) and \((t_2,q_2) \text{.}\)
If variable \(t \) represents time, then we can interpret this formula in words as
\begin{equation*} \text{avg rate} = \frac{\text{accumulation}}{\text{duration}} \text{.} \end{equation*}

Remark 1.3.4.

The formula in Definition 1.3.3 is an example of what is called a difference quotient, as it is literally a “quotient of two differences.”
As suggested by the choice of placing \(t_1 \) and \(t_2 \) as the first coordinate in the data points, the quantity whose accumulation is used as the denominator in a rate ratio is usually considered to the be independent variable, while the other quantity is thought of as the dependent variable. That is, using the variables \(q \) and \(t \text{,}\) we think of variation in \(t \) as causing or “driving” the accumulation of \(q \text{.}\) We have chosen the variable \(t \) to represent the “general” independent variable instead of the more traditional variable \(x \) because we will usually consider time as the ultimate “independent variable,” and we want to invoke the intuition of a quantity varying over some period of time when we make general statements. However, in many situations the independent variable will represent something other than time. For example, in economics you might model variations in cost of production as the number of units being produced varies.
The following example from physics with time as the independent variable should be familiar to you.

Example 1.3.5. Average speed.

As you drive a vehicle, you are accumulating distance from your starting position. You may also think of this as varying your position over time. Suppose you drive 100 km in about an hour. If we let \(d \) represent distance from the starting point of the trip and \(t \) represent time, then
\begin{equation*} \slope{d}{t} = \frac{100}{1} = 100 \end{equation*}
represents your average speed in kilometres per hour.

Example 1.3.6. Average rate of return of an investment.

You check your investment account and find a balance of \(\$10,385.92 \text{.}\) Four weeks later, you check again and find a balance of \(\$10,593.64 \text{.}\) So over that time period, your account has accumulated
\begin{equation*} 10,593.64 - 10,385.92 = 207.72 \end{equation*}
dollars, at an average rate of
\begin{equation*} \frac{207.72}{4} = 51.93 \end{equation*}
dollars per week.
We will study average rate of accumulation further in Chapter 5.

Section 1.4 Constant accumulation

Normally we think of rate of accumulation as itself being a quantity that varies. For example, in Example 1.3.5, you likely didn’t leave your parking spot at 100 km⁄h and you likely didn’t crash into your destination at 100 km⁄h. Along the way, you would have sped up and slowed down at various points of the trip, perhaps even stopped completely at traffic lights. If we calculated an average rate of variation in position over the first five minutes of the trip, while you were travelling on city streets to get out onto the highway, the result would likely have been much lower than 100 km⁄h.
A pair of quantities that accumulate in tandem so that the average rate of accumulation between them is always the same is a special situation.

Example 1.4.1. Varying quantities at a constant rate.

Suppose \(q \) and \(t \) are quantities so that \(q \) varies as \(t \) varies, and it is observed that
\begin{equation*} \slope{q}{t} = \frac{1}{2} \end{equation*}
seems to always be true between every pair of data points. Then we can predict the quantity \(q \) at any level of quantity \(t \) using only a single known data point. For example, suppose we know an “initial” data point where \(q = 1 \) when \(t = 0 \text{.}\) Then using \(q_1 = 1 \) and \(t_1 = 0 \) in any average rate calculation will tell us the second data point. For example, if we use \(t = 4 \) for the second data point, we can calculate the corresponding \(q \)-value as follows.
\begin{align*} \slope{q}{t} \amp = \frac{1}{2} \\ \frac{q_2 - 1}{t_2 - 0} \amp = \frac{1}{2} \\ \frac{q_2 - 1}{4 - 0} \amp = \frac{1}{2} \\ q_2 - 1 \amp = \frac{4}{2} \\ q_2 \amp = 3 \end{align*}
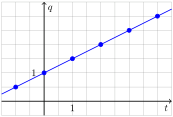
We can use a similar calculation to determine the \(q \)-value corresponding to any value of \(t \text{.}\) In Figure 1.4.2, we have plotted some example data points obtained in this way on a set of \(tq \)-axes. From these data points, we observe a clear linear relationship between \(q \) and \(t \text{.}\)
Data points and trend line for a quantity accumulating at a constant rate.
Data points are plotted on a set of \(tq \)-axes, at coordinates \((-1,0.5), (0,1), (1,1.5), (2,2), (3,2.5), (4,3) \text{.}\) These points appear in a linear pattern, and a line is drawn through them.
Figure 1.4.2. Data points and trend line for a quantity accumulating at a constant rate.
Graphically, when a quantity exhibits a constant rate of accumulation relative to another, we can plot the relationship between \(q \) and \(t \) on a set of \(tq \)-axes and obtain a line with equation as in Pattern 1.4.3, where the slope of the line is
\begin{equation*} \slope{q}{t} \end{equation*}
and the “\(q \)-intercept” is at the data point \((0,q_0) \text{.}\)

Example 1.4.4. Determining linear relation for a quantity with constant rate of accumulation.

Suppose \(q \) and \(t \) are quantities so that \(q \) exhibits a constant rate of accumulation relative to \(t \text{,}\) with
\begin{equation*} \slope{q}{t} = -2 \end{equation*}
for all pairs of data points. Then using Pattern 1.4.3, we can say that
\begin{equation*} q = -2 t + q_0 \text{.} \end{equation*}
However, suppose we don’t know the data point at \(t = 0 \text{,}\) but instead know that \(q = 1 \) when \(t = 3 \text{.}\) Then
\begin{gather*} q = -2 t + q_0 \\ 1 = -2 \cdot 3 + q_0 \\ 1 = q_0 - 6 \\ q_0 = 7 \text{.} \end{gather*}
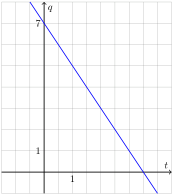
With this information, we can plot the linear relationship between \(q \) and \(t \) on a set of \(tq \)-axes.
Graph and linear relationship for a quantity accumulating at a constant, negative rate.
The line with equation \(q = -2 t + 7 \) is drawn on a set of \(tq \)-axes. The line slopes downwards, crossing the vertical axis at \(q = 7 \) and then crossing the horizontal axis at \(t = 3.5 \text{.}\)
Figure 1.4.5. Linear relationship for a quantity accumulating at a constant, negative rate.
In Figure 1.4.5, we see that the plotted line crosses the \(q \)-axis at \(q_0 = 7 \text{.}\) Interpreting
\begin{equation*} \slope{q}{t} = -2 \end{equation*}
as the variation in \(q \) per unit variation in \(t \), we also see that the plotted line descends two units for each unit increase in \(t \text{.}\)
Compare the graphs in Figure 1.4.2 and Figure 1.4.5. In the first graph, the line goes up as it goes to the right, as we expect from its positive slope. In the second graph, the line goes down as it goes to the right, as we expect from its negative slope.
The average of a constant value is just that constant value, so in the case of a constant rate \(r \) off accumulation, \(\avg{r} = r \) over every time period. So if the constant rate is known and we would like to compute an accumulation value \(\change{q} \text{,}\) we don’t actually need to know the initial and final quantity values \(q_1, q_2 \text{,}\) and instead can just reverse the formula in Definition 1.3.3.

Example 1.4.8. Accumulation of salary for constant rate of pay.

In 2026, the minimum wage in Alberta, Canada is $15 per hour. This is a constant rate of pay \(r = 15 \text{.}\) If the worker is paid daily for each eight-hour shift with no deductions, and \(q(t) \) represents the amount in the worker’s bank account at time \(t \text{,}\) then we may calculate the daily accumulation of money in the account by
\begin{align*} \change{q} \amp = r \cdot \change{t} \\ \amp = 15 \times 8 \\ \amp = 120 \text{.} \end{align*}
Note that this does not represent the amount of money in the worker’s account at the end of any working day, as that also depends on the initial amount at the beginning of the day. If that initial amount is known, then Pattern 1.2.4 could be applied to determine the final account balance at the end of the day.